AWQ Activation-aware Weight Quantization for LLM Compression and Acceleration
- Doc no.
- KKZ-TN-075
- Date
- 2025-07-28
- GMT day
- 2025:209
- Est. read
- 3 min
Extensive Reading
01Author Info#
02Background#
Quantization is vital for running LLM on edge devices.
03Challenges#
- Quantization-aware training (QAT) is not efficient due to the high training cost.
- Post-training quantization (PTQ) suffers from large accuracy degradation under a low-bit setting.
04Insights#
- Not all weights in an LLM are equally important.
- Protecting only 1% salient weights can greatly reduce quantization error.
- To identify salient weight channels, we should refer to the activation distribution, not weights.
- Mixed-precision format is not hardware-efficient, we can employ activation-aware scaling.
05Approaches#
5.1Activation-aware Weight Quantization#
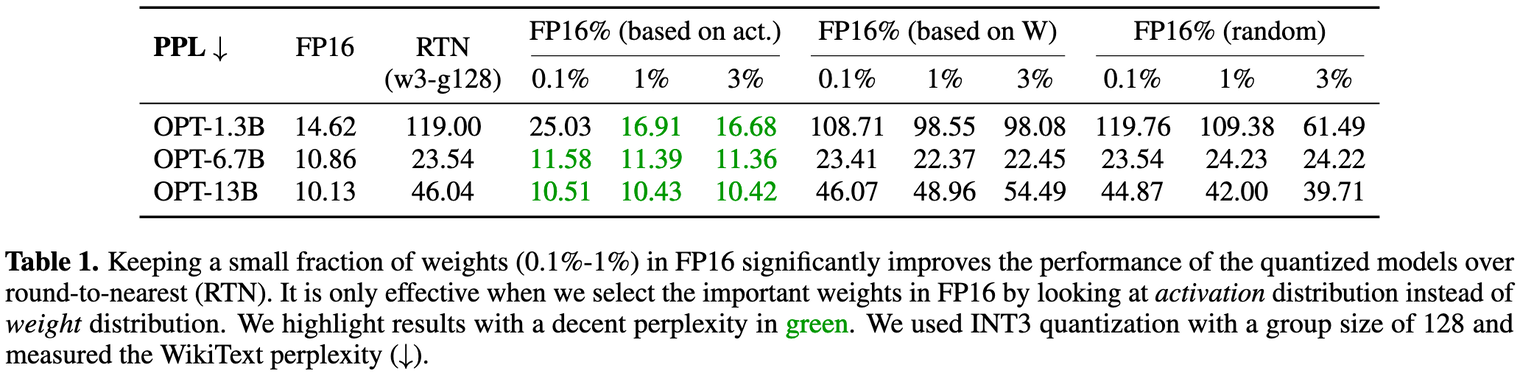
直接使用 round-to-nearest(RTN) 量化方法会导致 PPL 指标增大,作者分别使用三种策略来保留部分权重为 FP16 格式:随机,根据权重矩阵,根据激活值大小。
实验发现根据激活值大小策略效果最好,所以提出了假设:the input features with larger magnitudes are generally more important.
论文中将这种权重称为 salient weights.
直接保留 FP16 格式的 salient weights 无疑是最直接的,但这种精度混合格式对硬件并不友好,所以 AWQ 提出了通过 per-channel scaling 来保护 salient weights.
这部分的核心思想是:通过在量化前“放大”重要的权重,可以有效减小它在量化过程中产生的误差。
论文中进行了简单的公式推导,得到的结论是:将权重 放大 倍,成功地将其量化误差缩小了约 倍。
- 固定位宽下,量化步长 是由组内最大幅度定的;你把某个“被保护”的权重放大 倍,相当于让信号更“占格”,四舍五入仍是“最多半格”的误差,但随后又整体除以 回到原标度,于是误差也被同步除以 。
- 只要不把组的 推高(),这个 的误差缩减就成立;一旦把组的最大值顶高了(),其它未放大的权重误差就会被放大,出现全局折中。论文里对 变化比例、PPL 与 的关系也做了统计与实证。
一句话:先把“重要通道”的信号放大,再整体除回去,在不改算子理想输出的前提下,把“每次四舍五入最多半格”的绝对误差按 比例缩小;这就是 AWQ 用 per-channel scaling 保护 salient weights 的数学基础。
- 放大 :只在 离线量化前 对权重施加(为了减少量化误差)。
- 除以 :只在 推理时输入流 进行一次性代偿(保证功能等价)。
- 对模型使用者而言,最终调用时就是一次普通的矩阵乘法,只不过里面“隐藏”了一个 scaling 过程;不需要手工再做两次乘除。
与其手动指定一个固定的缩放比例(比如 s=2),不如设计一种方法来自动地、为每一个权重通道(channel)找到一个最优的缩放比例,从而让整个模型的量化误差最小。
AWQ 将这个问题形式化为一个优化的问题:找到一组缩放因子 s(每个输入通道对应一个),使得“权重乘以 s 再量化,然后输入除以 s ”这一系列操作之后得到的结果,与原始的、未经量化的结果之间的差距最小。
直接求解很困难,但是我们可以简化 的范围:
- :每个通道激活值的平均大小。这个值可以从一小部分校准数据中提前统计出来。
- :一个介于 0 和 1 之间的超参数。
至此,寻找 的问题可以简化为寻找一个全局的超参数 。
5.2TinyChat#
4.1 小节的实验结论也很有参考性。
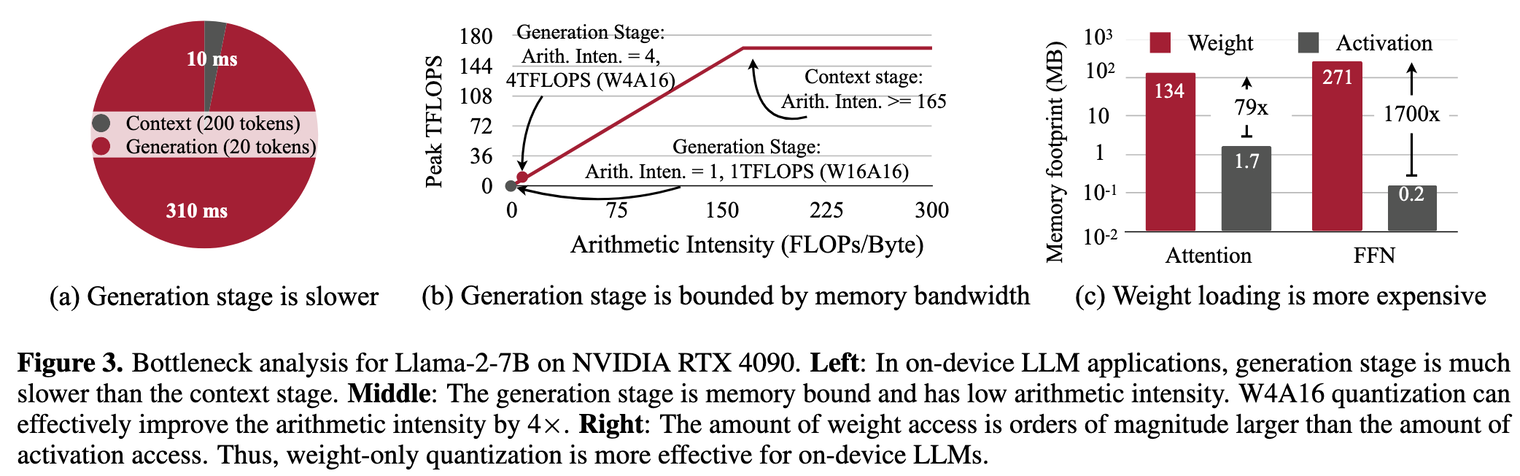
- The generation phase is substantially slower than the context stage.
- The generation phase is memory-bounded (pretty small arithmetic intensity)
- Weight access dominates the memory traffic for on-device LLMs.
- Quantizing the model weights to 4 bit integers will approximately increase the arithmetic intensity to 4 FLOPs/Byte.
论文还开发了一个名为 TinyChat 的高效推理框架,通过以下关键技术实现了显著加速:
- On-the-fly dequantization:在计算过程中,将 4 位权重实时地恢复到 16 位浮点数,并与矩阵乘法等计算操作融合,避免了将反量化后的权重写回内存,减少了访存开销。
- Kernel fusion:将多个独立的操作(如注意力计算中的 QKV 投影、层归一化等)融合成一个单一的计算核心,大大减少了 GPU 核心的启动开销,这对于延迟极低的操作尤为重要。
- SIMD-aware weight packing:针对 CPU 等具有 SIMD 架构的设备,设计了特定的权重打包和重排方式,使得在运行时可以利用 SIMD 指令高效地解包权重,进一步提升反量化速度。
06Evaluation#
效果好,通用性强!
07Thoughts#
7.1When Reading#
第三章整体的逻辑很清晰:
- Selecting weights based on activation magnitude can significantly improve the performance despite keeping only 0.1%-1% of the channels in FP16.(&3.1)
- But mixed-precision format is not hardware-efficient.
- Instead of preserving the salient weights in FP16, we can employ activation-aware scaling. (&3.2)
- Instead of manually specifying a fixed scaling factor (e.g., s=2), a method should be designed to automatically find an optimal scaling factor for each weight channel, thereby minimizing the overall model's quantization error. (&3.3)
看完之后的感受:Simple but effective!