Quest Query-Aware Sparsity for Efficient Long-Context LLM Inference
- Doc no.
- KKZ-TN-111
- Date
- 2025-11-13
- GMT day
- 2025:317
- Est. read
- 2 min
Extensive Reading
01Author Info#
02Background#
In long-context inference:
- The KV cache grows linearly with context length ().
- At each decoding step, the model must read the entire KV cache to compute attention.
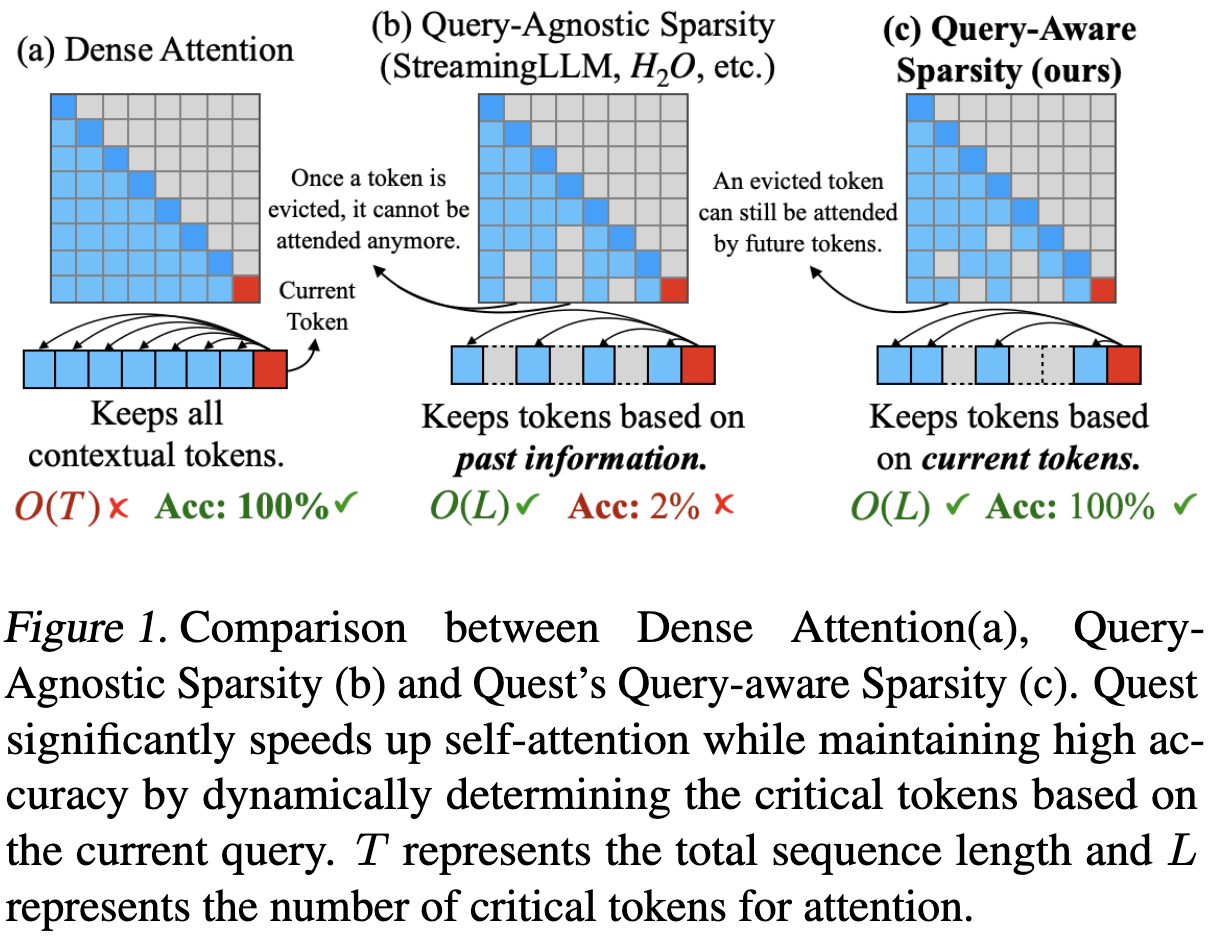
Existing works recognize there is small part of tokens that can domoinate the accuracy of token generation, and they choose to evict unimportant tokens:
- StreamingLLM keeps a sliding window plus a few “anchor” tokens.
- H2O, TOVA, etc., use heuristics or statistics to permanently drop “less important” tokens.
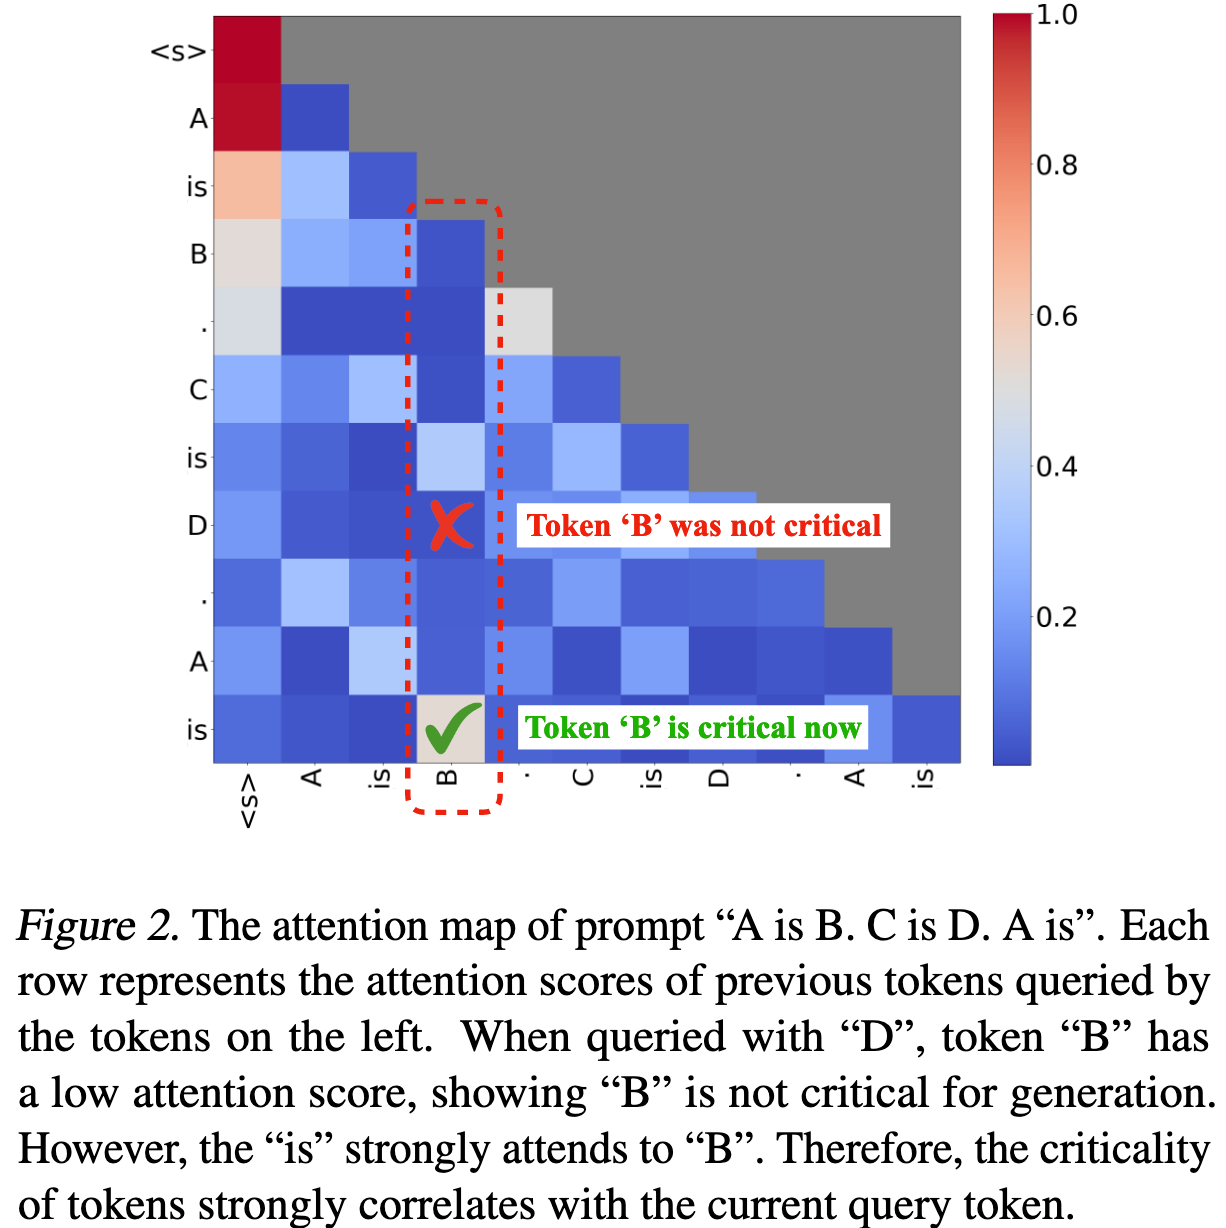
Once a token is evicted, it’s gone. BUT, the important tokens are Query-dependent.
Given a sentence: "A is B. C is D. A is." The token B's importance varies (shown in Figure 2).
03Insights#
Don't delete KV, just read the right part.
04Approaches#
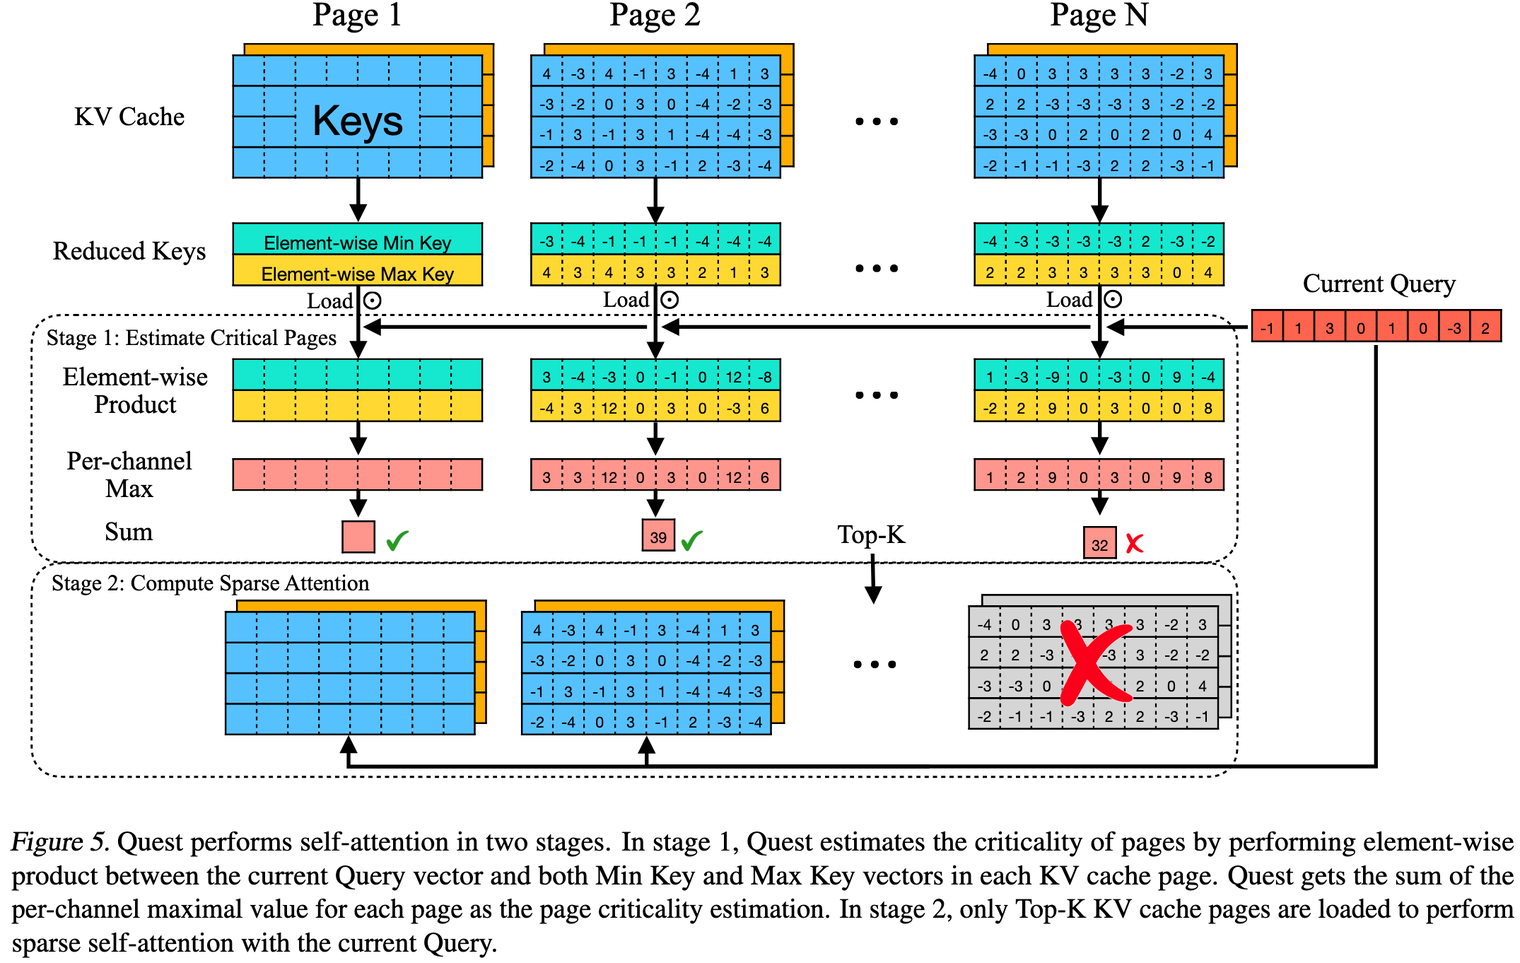
KV caches are organized in the form of pages (according to the PagedAttention).
Quest maintain some metadata per page: (two vectors)
- (): element-wise minimum over all keys in this page.
- (): element-wise maximum over all keys in this page.
Given the metadata (), we know that for any key () in the page, each dimension () must lie in (). So for dimension (i):
- If (), the maximum product happens at ().
- If (), the maximum product happens at ().
So we can define:
Then the upper bound of the dot product between () and any key in that page is:
So we can run a Top-k selection over pages using these scores
Overall workflow:
- Query-aware page selection
- Sparse Attention on Selected Pages
05Evaluation#
06Thoughts#
6.1When Reading#
Talk is cheap, show me the code -- CUDA everywhere